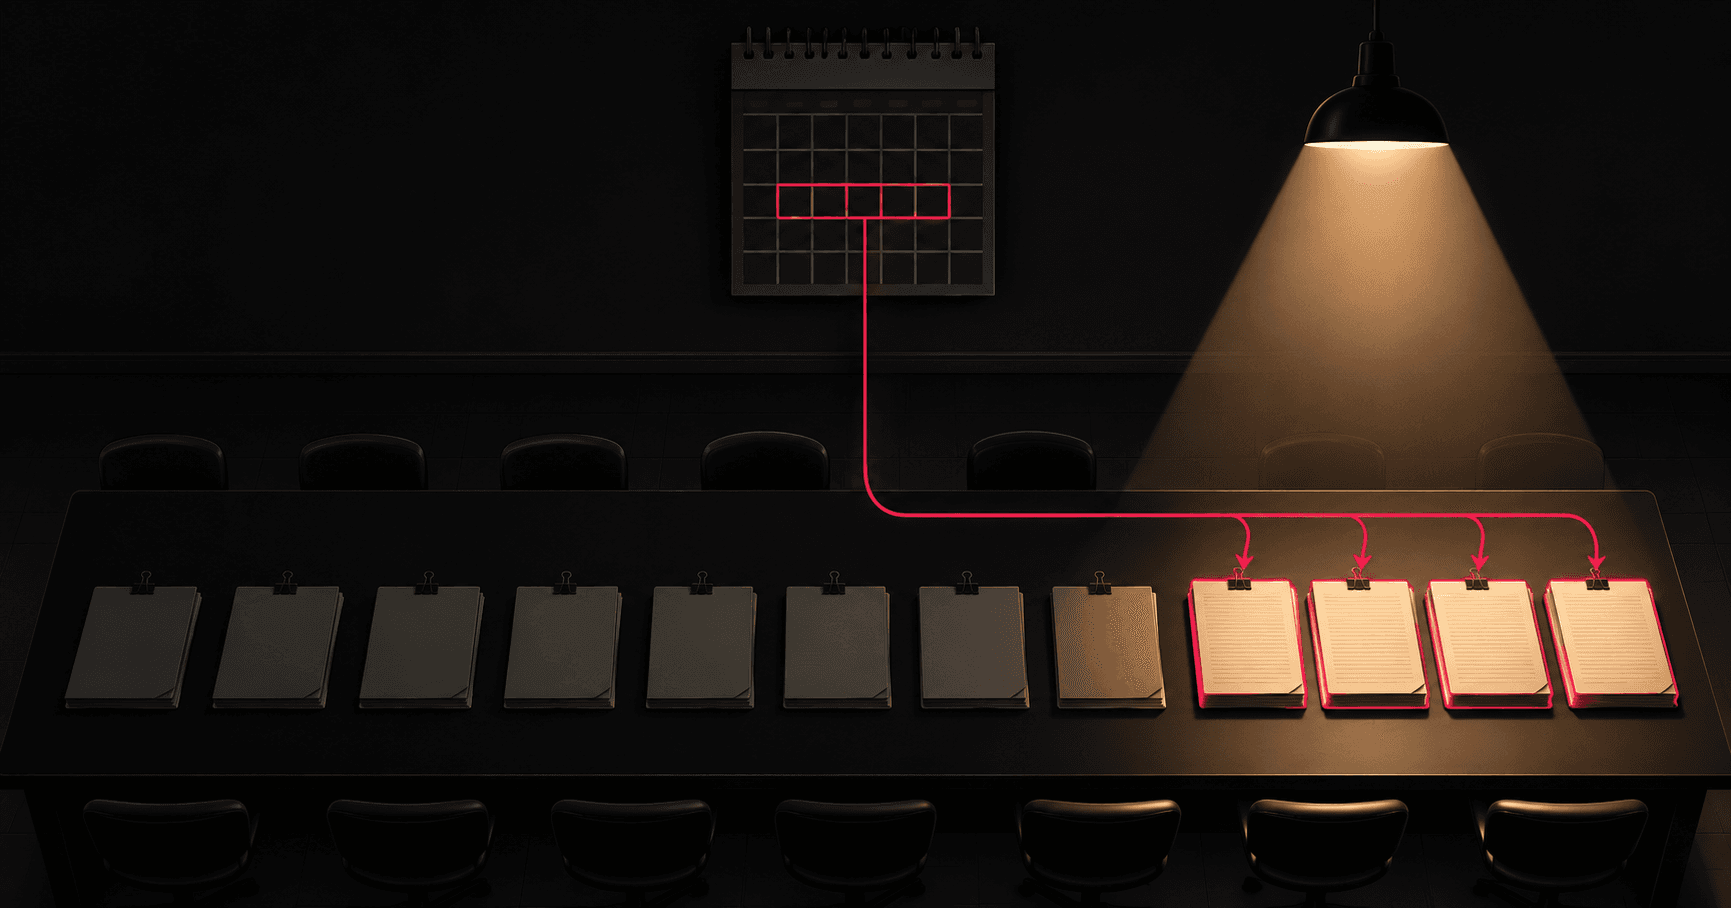
A calibration meeting runs for forty minutes. Twelve names, four slots, seven managers around a table and one director who will sign whatever the table agrees.
The fifth name takes ninety seconds. Her manager says she has had a strong year, lists three things, and finishes with I think she's close. Somebody asks what she owns. Her manager says she has been the glue on the platform team for two years, that onboarding runs because of her, that two incidents last quarter were short because she was the one who understood the dependency. Somebody else says that's all true and asks again what she owns.
Nobody in that room lies. Nobody argues against her. At the end she is ranked fifth of twelve, four people are promoted, and she is told the following week that she is not quite ready and should work on visibility.
The meeting did not decide that. The meeting ratified it. The decision was taken nine months earlier, in March, by one person allocating work on a whiteboard — and that person has no idea they made it.
What the Packet Can Hold
Every organisation that promotes at scale needs a format. A packet, a case, a document — a fixed set of fields that a committee can read quickly and compare against ten others.
The fields are always roughly these. What did this person own. What shipped. What changed as a result, in numbers. What scope do they hold now and what scope would they hold next. Supporting statements from people who worked with them.
That format is a filter, and it was designed for honest reasons: comparability, protection against favouritism, a written record that survives a manager leaving. It does those jobs well. What it cannot do is hold anything that failed to leave an artifact behind.
So the packet has no field for the incident that did not happen because someone noticed a bad assumption in a design review. No field for the engineer who did not quit because somebody spent a month of lunches talking them through a rough patch. No field for the system that is comprehensible two years later because one person kept rewriting the documentation nobody asked for. No field for the meetings where the actual decision got made before the meeting where it was recorded.
Part 1 named the category: glue work, Tanya Reilly's term for the work that holds a team together and almost never appears in a promotion case. The point to add here is structural. Glue work goes unrewarded because the organisation forgot to value it, and also because the form has no box for it. Every promotion system in the industry reads artifacts. Glue work is defined by leaving none.
A promotion format that reads only artifacts is a correct and defensible system for ranking artifacts. It becomes a filter on people the moment artifacts are handed out unevenly — and handing them out is a separate decision, made by a different person, at a different time of year, with no review attached to it.
The Decision Was Made in March
Here is the sequence as it actually runs, in a company doing nothing wrong on purpose.
March. A team plans the year. There is a new service to build, a migration to finish, a legacy system to keep alive, and the ordinary work of keeping a team functioning. A manager with eight reports assigns it. The new service goes to the person who has been asking for it. The migration goes to the person who finished the last one. The legacy system goes to the person who knows it. The glue goes to whoever has been doing it, because they are good at it and because the team would notice immediately if they stopped.
Nobody in that room experiences this as a promotion decision. It feels like resourcing.
June. The new service ships to a first internal customer. The migration is 60 percent done and has already prevented one class of outage. The legacy system has not fallen over. Onboarding has absorbed three new hires without incident, two of whom will later say in a survey that they ramped up faster here than anywhere they have worked.
October. Packets are written. The new service is an artifact — named, shipped, with a number attached. The migration is an artifact, slightly harder to write up, and the person who did it will undersell it because the work was unglamorous. The legacy system produces a packet that reads as maintenance, which is a word that has never promoted anyone. And the fourth packet is a list of adjectives.
December. Four slots. Twelve packets. The ranking takes forty minutes and feels rigorous, because it is rigorous. Everyone reads carefully. Everyone compares against a written bar. The outcome was fixed in March.
This is the part that makes the whole thing durable. Audit the promotion process and you will find it clean — written criteria, multiple readers, a calibration step that exists precisely to remove individual bias, documented outcomes. The bias entered the system three quarters upstream, in a decision that nobody classifies as part of the promotion process at all.
Scope assignment is the promotion decision. Everything after it is bookkeeping, performed carefully, by people who believe they are deciding.
The Four Things Calibration Actually Does
Calibration exists for a real reason. Left alone, one manager rates everyone exceptional and another rates nobody above solid, and the two populations are indistinguishable on any other measure. Putting the managers in a room together fixes that, and it is worth keeping.
What the room does beyond that is less examined.
Inside the forty minutes.
- It ranks packets against each other. The written bar frames the discussion, and the live question in the room is which of these twelve goes above which. A packet is a document about work, filtered through a manager's writing ability — so the ranking is partly a ranking of managers.
- It applies a budget that nobody in the room states out loud. Four slots came down from finance in September. The conversation is conducted entirely in the language of readiness.
- It converts a capacity constraint into a verdict about a person. No slots left and not quite ready produce the same outcome and only one of them gets said. The second one goes into the person's file and their head.
- It rewards whoever argues best. A manager who prepares, who has pre-briefed two peers, who can answer what does she own with one sentence and a number, moves their report up the list. This is sponsorship, described mechanically, and it is the whole of it.
Two smaller effects run underneath all four.
Recency compresses the year. A twelve-month performance arrives in a room where everyone's clearest memory is the last eight weeks, and the person who shipped something visible in November is argued for with more detail than the person whose best quarter was in spring. Nobody intends this and almost nobody corrects for it.
And ambiguity flows downhill into whichever language is hardest to challenge. A room that cannot say we ran out of slots will reach instead for presence, readiness, visibility, maturity — words with no observable referent, which is exactly why they are available. They cannot be contradicted, so they survive the meeting.
The Reason Is Written Afterwards
Which brings us to the feedback conversation, and to the most useful thing in this article for anyone who has ever sat through one.
When the reason given for a decision has no example attached, the most common explanation is that no example exists — because the reason was generated after the decision, to explain an outcome produced by scope and slots.
That is why the three sentences are always the same three sentences. You need more visibility. Work on your executive presence. You're close, but not quite ready. Those three sentences do a job. Each one is unfalsifiable, each one locates the remaining work inside the candidate, and each one leaves the manager with something to say that is not the budget was four and you were fifth, and the reason you were fifth was decided in March.
Part 1 argued that unfalsifiable feedback should be refused in writing, in calibration, as a rule. The mechanism is the reason that rule bites. Banning the language forces the room to state the actual cause, and the actual cause is usually either a capacity constraint or an assignment pattern — both of which are facts about the organisation, and both of which can be fixed.
A candidate who hears not quite ready three cycles running and cannot extract a single specific instance has been handed a decision with its reason removed. The honest response to it is a question: was this a bar question or a slot question?
What the Numbers Underneath Look Like
The mechanism is gender-neutral in its design and reliably gendered in its output, because the inputs it reads are distributed unevenly before it ever runs.
McKinsey and LeanIn have measured the first promotion into management for eleven years. In the 2025 edition, for every 100 men promoted into a manager role, 93 women were. For women of colour the figure is 74 — and that number was 81 in the previous year's report. One cycle of this machine running, in one direction, across the companies in that study.
Sponsorship sits upstream of the calibration room and is distributed the same way: 31 percent of women have a sponsor at entry level, against 45 percent of men. Recall what a sponsor does in the forty minutes. The gap in advocacy is a gap in the one input that demonstrably moves a ranking.
The cumulative shape across industries is a staircase that narrows at every step — roughly 51 percent of entry-level roles, 39 percent of manager roles, 29 percent of executive roles. In engineering the drop arrives earlier and harder, with recent survey work putting women at about 14 percent of manager roles and about 9 percent of director roles. That particular survey is small, a few hundred respondents, so treat the two figures as a direction rather than a measurement — the direction is corroborated by everything around it.
Now the part the data cannot say, and the reason this article exists.
None of the four mechanisms above contains a gender term. They run on whoever gets handed the glue. In organisations where that happens to fall along lines of race, or class, or accent, or who went to the same university as the person allocating work, or who is in the office on the days the director is, the same machine produces the same shape with a different group at the bottom of it. The gender data is simply the best-measured instance, because somebody has been counting it for eleven years.
A system that promotes on artifacts and assigns artifacts informally will reproduce whatever informal pattern exists in the room, year after year, with a clean audit trail the whole way.
And one more thing the numbers cannot carry on their own. Eleven percent of the Fortune 500 is a record, set after seventy-two years of lists. It is a real improvement and it was won by people who did this work. The mechanism described here argues something narrower than despair: the movable part has been misidentified all along. Mirrors and workshops sit downstream of a whiteboard in March.
What Good Looks Like
The organisations that have fixed this have fixed it in roughly five ways, and four of them are cheap.
Publish the rubric with worked examples, before the cycle. Not a list of adjectives — two or three anonymised packets that cleared the bar last year and one that did not, with the reasoning. A bar that can only be learned by failing to clear it is a bar that advantages whoever has been told about it privately.
Review scope assignment as a distribution, every quarter. This is the lever, and almost nobody pulls it. Pull the last four quarters of significant projects, list who got each one, and look at the pattern. Then do the same for the glue: onboarding, incident write-ups, documentation, the cross-team negotiation, interview load. Fifteen minutes, once a quarter, against a decision that currently gets made in March and reviewed never.
Say the slot count out loud, in the room and afterwards. There were four slots and twelve strong packets is a sentence that costs nothing and is true. It separates a capacity decision from a readiness verdict, and it stops the organisation from writing a permanent record about a person when what happened was a budget.
Make glue work produce an artifact on purpose. If onboarding matters, make it a named system with an owner, a documented process and a measured ramp time — then it has a field in the packet. This converts invisible labour into promotable work without pretending the labour was ever optional. It also reveals how much of it one person has been carrying.
And the expensive one: give the glue to the people who need the artifact. Rotating unpromotable work is the only one of these five that costs real output in the short term, because the person who has been doing it is better at it. Every organisation that has genuinely moved its first-rung numbers has paid that price somewhere.
There is a warning from Part 1 that applies directly to this list. India required one woman director on certain boards and got one woman director — representation roughly tripled while operating authority stayed where it was, because the rule specified a seat. A promotion-rate target lands the same way. Write the requirement as a number promoted and you will get the number promoted, from whichever pool is already closest to the bar. Write it about who gets assigned the work that makes a packet, and you change what the pool is made of.
If You Want the Next Rung
The useful move is early and it is boring.
Ask, in writing, at the start of the cycle: what will my packet be written on? Ask your manager to name the artifact — the system, the scope, the number. If the answer is a list of adjectives, the packet in December will be a list of adjectives. March is when this is negotiable and October is when it is not.
Negotiate scope rather than performance. Working harder inside an assignment that produces no artifact returns nothing the format can read. The conversation that pays is about what you are assigned next, and it is a different conversation from the one about how you are doing.
Keep the glue and make it visible as a thing. The answer to what do you own cannot be a feeling. It can be a named onboarding programme with a ramp-time number, a runbook that cut an incident class, a design review process with an outcome attached. Same work, in a form the committee is able to read.
Find out who will be in the room. Not a mentor — someone senior who will be present at calibration and can answer what does she own in one sentence. Ask them directly to do that, and give them the sentence. Most people say yes, and most people are never asked.
And when the answer comes back as readiness, ask which it was. Was this a bar question or a slot question, and if it was the bar, what is the specific instance? Asked calmly, once, it is a fair question, and the answer tells you whether to invest another year here.
None of this makes the system fair. It is how to do well inside the system as it currently runs, which is the situation of nearly everyone reading this — and the five practices in the previous section are what the other chair owes in return.
If You Assign the Work
If you are the person at the whiteboard in March, the entire article is addressed to you, and your lever is larger than anyone else's in the chain.
Run the assignment audit before you plan the year, not after. Last four quarters, every significant project, every piece of glue, names against each. You will know within ten minutes whether you have a pattern. Most managers do, and almost none have looked.
Tell each person what their packet will be written on, in March. One sentence each. It is the single highest-leverage conversation available to you and it takes an afternoon for a team of eight. It also exposes, immediately, which of your reports you have quietly written off for the year.
Write the packet as well for your quietest report as for your most self-promoting one. The ranking is partly a ranking of your writing. That is unfair in a way you personally can fix, this cycle, for free.
Say the number of slots. To the room and to the people who did not get one.
Refuse readiness language without an instance — yours and everyone else's. If you cannot state what the person would have had to do differently, what you are holding is a ranking, and the ranking came from somewhere.
Nobody in That Room Voted Against Her
Go back to the forty minutes at the start.
Every statement made in that meeting was true. Her manager praised her sincerely. The question what does she own was a fair question, asked in good faith, and it had no good answer. The bar was written down, the discussion followed it, four people were promoted on genuinely stronger packets, and the director signed a decision that an auditor would find faultless.
The honest version of that meeting would have taken four minutes. There were four slots. The twelve packets reflected the work assigned in March. Two of the twelve had been handed work that cannot be written up, and one of those two is the reason the platform team functions.
None of that was said, because the meeting has no vocabulary for it and no authority over it. The room where a promotion is decided has a whiteboard, a quarter's worth of projects, and one person deciding who gets which. It meets in March, it keeps no minutes, and nobody calls it a promotion meeting.
That is where to look.
This is Part 2 of The Unwritten Rules, a series on how corporations actually work — power, promotion, and who gets to grow. Part 1 takes apart impostor syndrome as a diagnosis and sets out the numbers this part explains. The promotion and sponsorship figures are from McKinsey and LeanIn's Women in the Workplace 2025, the eleventh edition of that study; the engineering manager and director shares come from a 2025 survey of around 300 women in engineering leadership and are directional rather than precise. The term glue work is Tanya Reilly's.