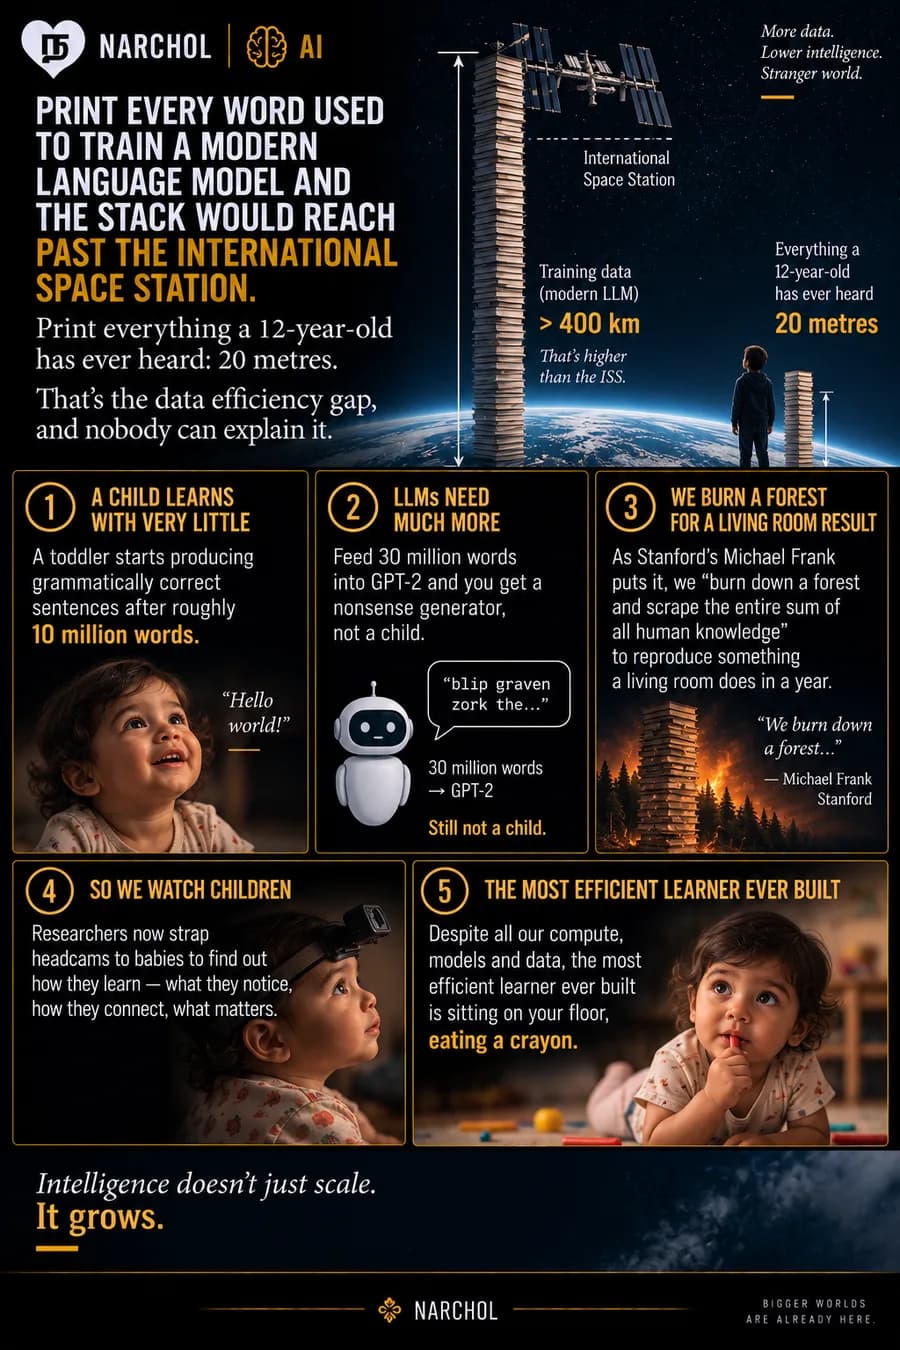
Print every word used to train a modern language model and the stack would reach past the International Space Station — over 400 kilometres. Print everything a twelve-year-old has ever heard and you get twenty metres.
That is the data efficiency gap, and nobody can explain it.
A toddler starts producing grammatically correct sentences after roughly ten million words. Feed thirty million words into GPT-2 and you get a nonsense generator. As Stanford's Michael Frank puts it, we "burn down a forest and scrape the entire sum of all human knowledge" to reproduce something a living room does in a year.
So researchers have started strapping headcams to babies — watching what a child notices, how they connect things, what matters to them — because the question has stopped being how to add more data.
Despite all our compute, models and data, the most efficient learner ever built is sitting on your floor, eating a crayon.
Intelligence doesn't just scale. It grows.