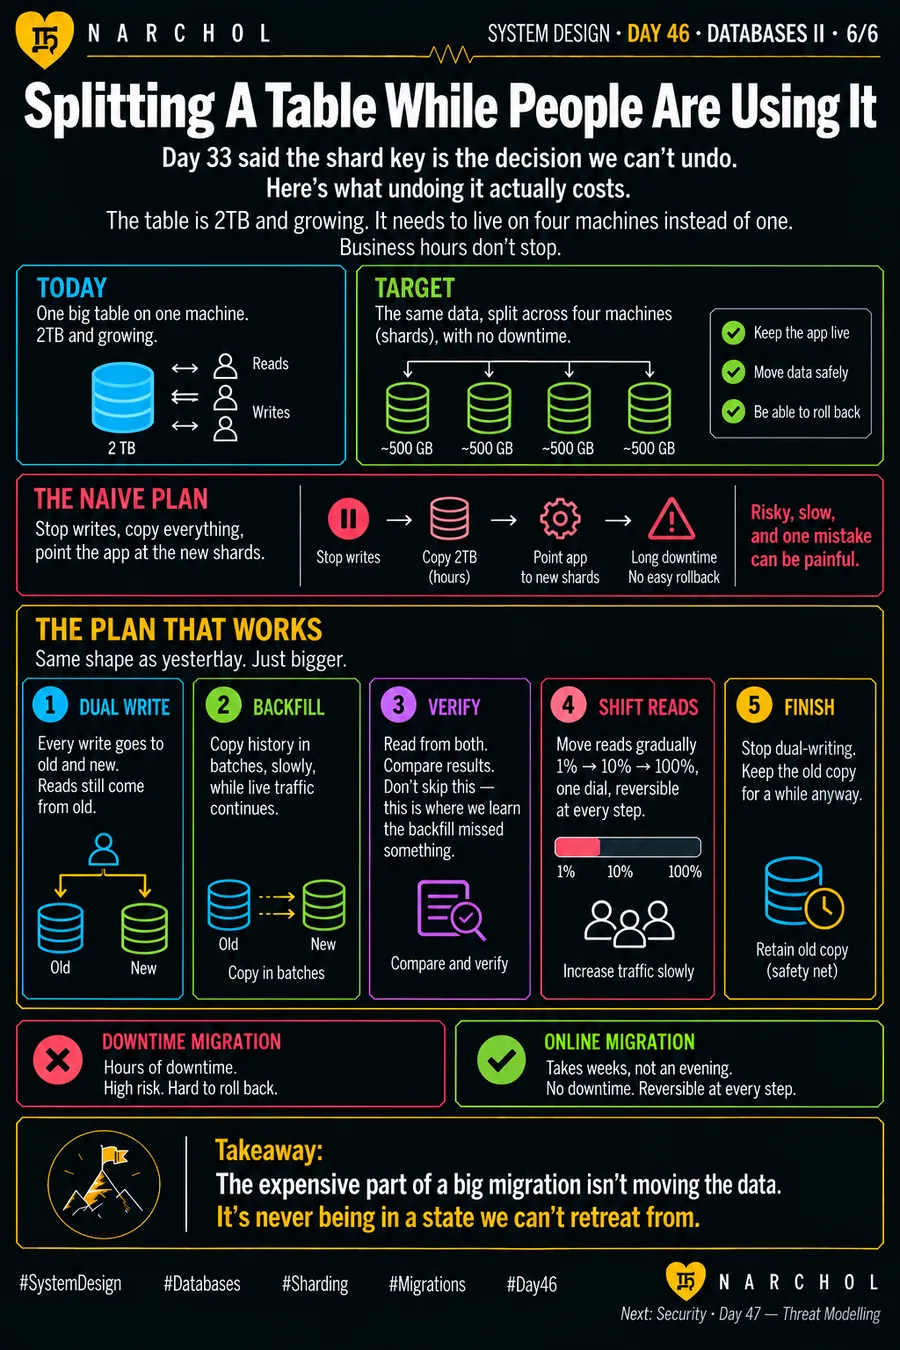
The table is 2TB and growing. It needs to live on four machines instead of one. Business hours don't stop.
The naive plan is to stop writes, copy everything, and point the app at the new shards. Hours of downtime, high risk, and no easy way back if something is wrong at the end of it.
The plan that works has five stages. Dual write — every write goes to old and new, reads still come from old. Backfill — copy history in batches while live traffic continues. Verify — read from both and compare, and don't skip this, because it is where you learn what the backfill missed. Shift reads — 1% to 10% to 100%, one dial, reversible at every step. Finish — stop dual-writing, and keep the old copy for a while anyway.
It takes weeks rather than an evening. Nothing is ever unrecoverable.
The expensive part of a big migration isn't moving the data. It's never being in a state we can't retreat from.