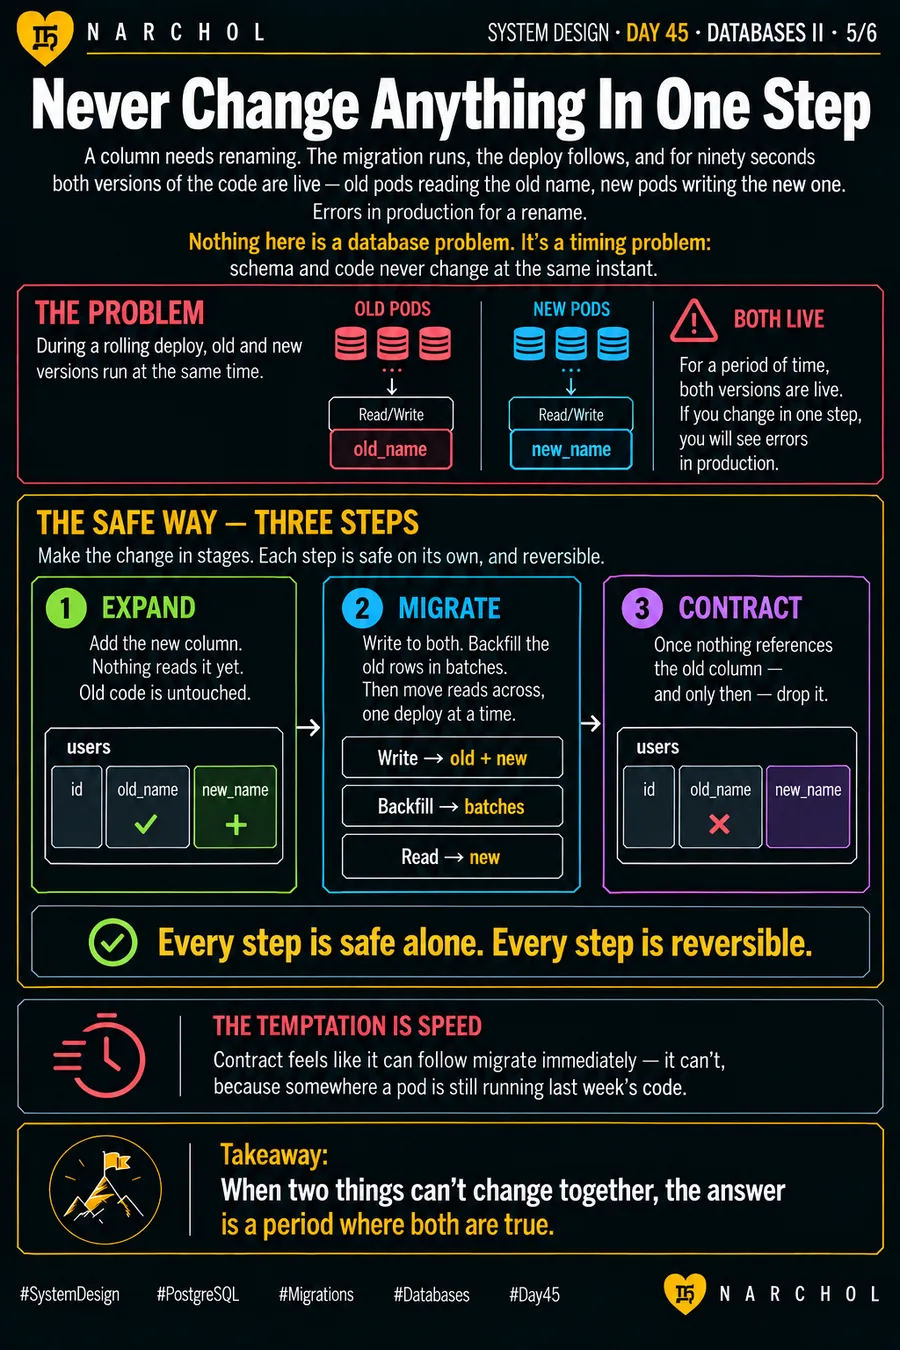
A column needs renaming. The migration runs, the deploy follows, and for ninety seconds both versions of the code are live — old pods reading the old name, new pods writing the new one. Errors in production, for a rename.
Nothing here is a database problem. It's a timing problem: schema and code never change at the same instant.
The safe way is three steps. Expand — add the new column, nothing reads it yet, old code untouched. Migrate — write to both, backfill the old rows in batches, then move reads across one deploy at a time. Contract — once nothing references the old column, and only then, drop it.
Every step is safe on its own and every step is reversible. The temptation is speed: contract feels like it can follow migrate immediately, and it can't, because somewhere a pod is still running last week's code.
When two things can't change together, the answer is a period where both are true.