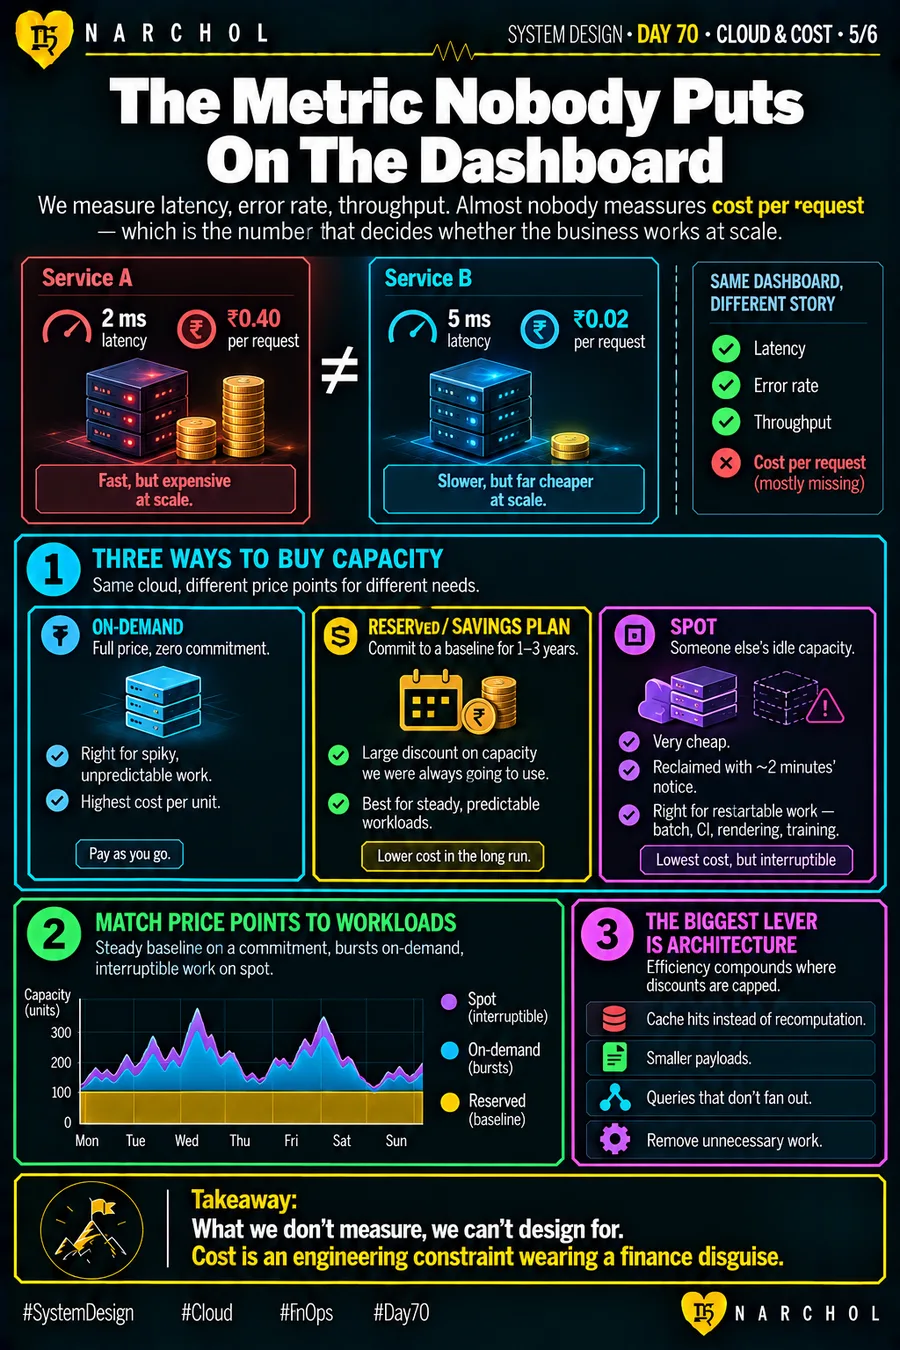
We measure latency, error rate, throughput. Almost nobody measures cost per request, which is the number that decides whether the business works at scale.
Two services can look identical on the dashboard. Service A answers in 2ms at ₹0.40 a request. Service B answers in 5ms at ₹0.02. Every panel we watch says A is the better service. At volume, A is twenty times more expensive to be three milliseconds quicker.
There are three ways to buy capacity, priced for different needs. On-demand is full price with zero commitment, right for spiky unpredictable work. Reserved instances and savings plans discount a baseline we were always going to use. Spot is someone else's idle capacity — very cheap, reclaimed at about two minutes' notice, and right for anything restartable: batch, CI, rendering, training.
Discounts are capped, though. The lever that compounds is architecture — a cache hit instead of a recomputation, a smaller payload, a query that doesn't fan out, work removed entirely.
What we don't measure, we can't design for. Cost is an engineering constraint wearing a finance disguise.